The latest from Light Origins
Light REACT: Building Resilient Whole-Body Intelligence for Scalable Deployment
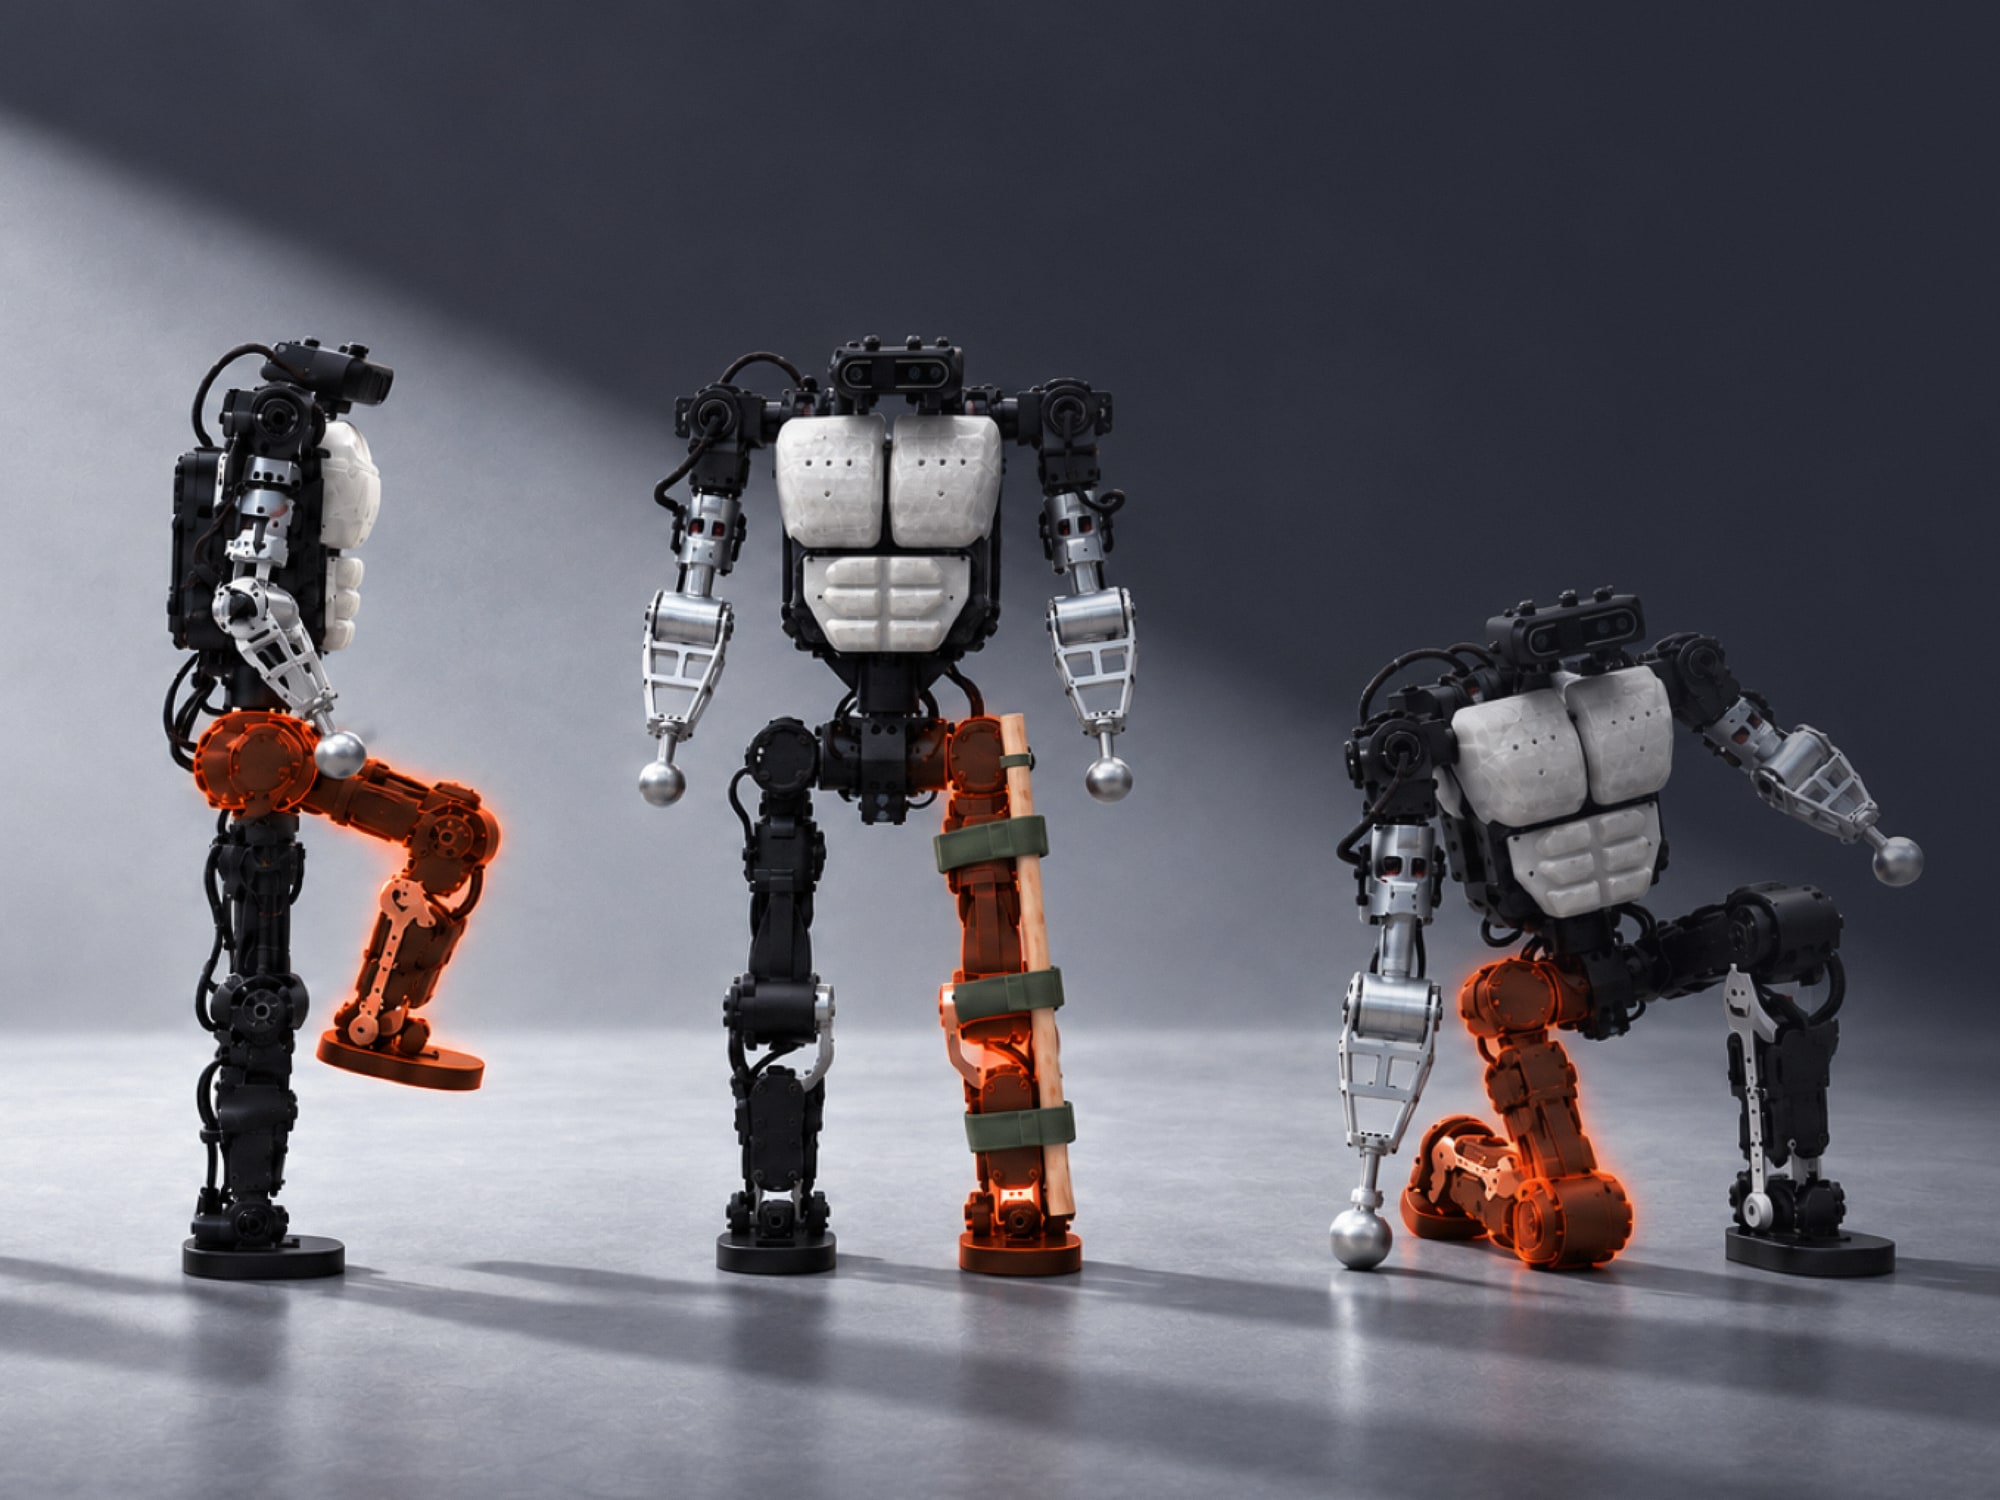
Light REACT is our first step toward scalable deployment at the control level. Transformer-based Whole-Body In-Context Learning uses recent physical interactions to infer the effects of external forces, hardware impairments, and environmental constraints, then respond with adaptive whole-body skills. Specialist training, multi-teacher distillation, and preference alignment encourage upright recovery and locomotion whenever feasible while retaining crawling as a fallback, reducing human intervention and task interruptions.
LightNav-0: Scaling Real2Sim2Real for Zero-Shot Generalist Navigation
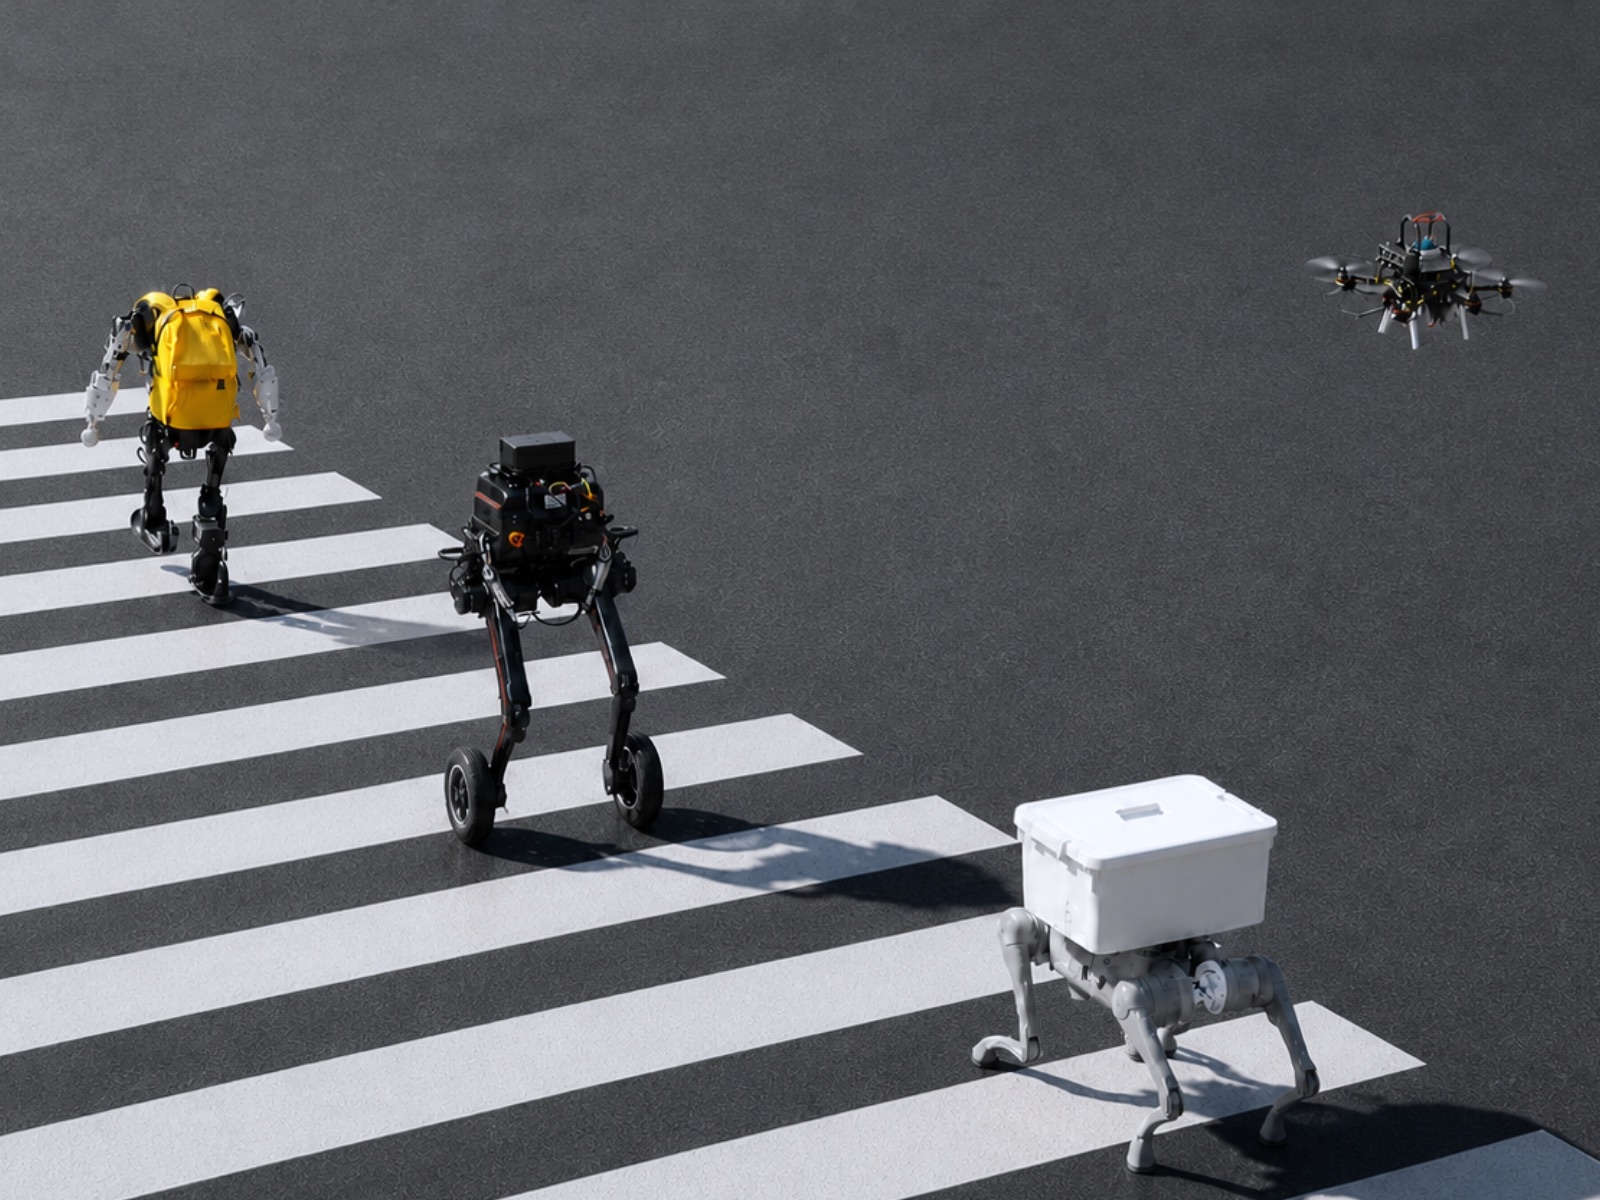
LightNav-0, our first general-purpose navigation brain, demonstrates zero-shot generalization across diverse robot embodiments, tasks, and scenes. Behind this capability is scalable alignment, enabled by a Real2Sim2Real data engine that turns 2,000+ real-world scenes into 4,000+ hours of simulation-based navigation experience.
Light Origins Closes Pre-A Round of Several Hundred Million Yuan to Build Physical AI Foundation Models, Founded by ChatGPT Core Contributor Roger Jiang
Round led by CAS Investment, with participation from China Merchants Venture Capital and Xiang He Capital; Light Origins to release results from scalable pre-training and demonstrations of cross-embodiment capabilities.
Roger Jiang: The Key to General‑Purpose Robots Resides in 10 Billion Hours of Internet Video
Why are foundation-model companies all moving into embodied AI right now, and how do we break the data scarcity? Roger Jiang: the data goldmine for general-purpose robots lies in 10 billion hours of internet video.
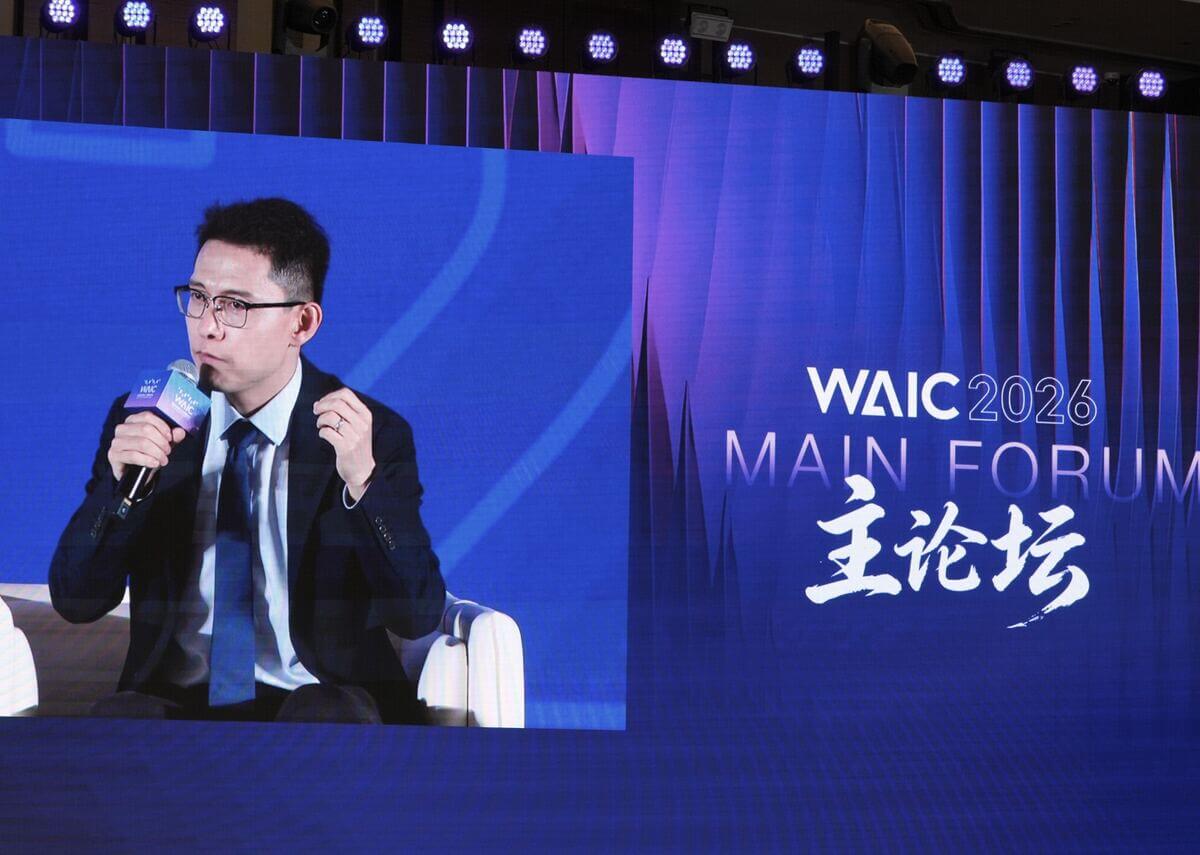
WAIC 2026 | Roger Jiang, ChatGPT Core Contributor: World Models Alone are Insufficient
A world model must predict both the next state and the next action — and predicting action matters more. Embodied AI still has to go through scalable pre-training, alignment and deployment.
LightParkour: Growing Humanoid Parkour Skills Through Real2Sim2Real
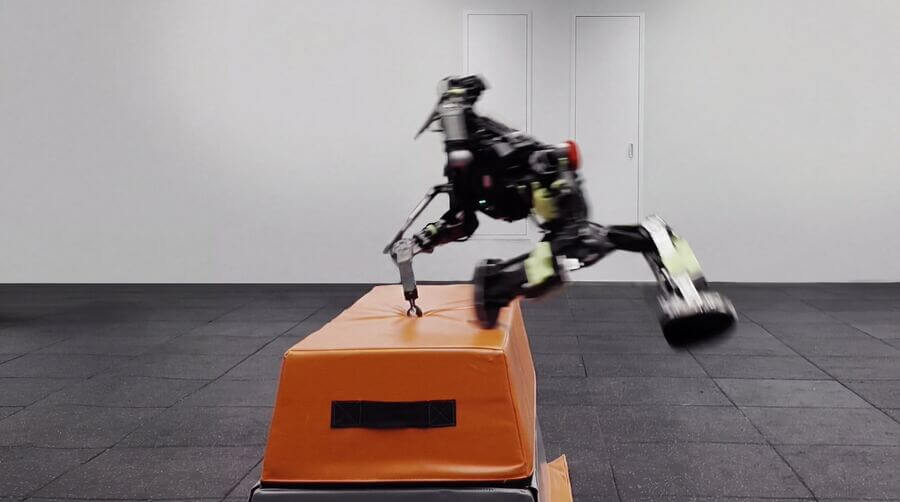
Ground a short human-motion seed in physics, grow it across terrain variation, and distill locomotion and whole-body skills into one deployable depth policy — running onboard Lightbot 0.